Aryan
ML Engineer
Aspiring Machine Learning Engineer with hands-on experience in building and deploying AI/ML applications. Skilled in Python, Scikit-learn, TensorFlow, NLP, and cloud technologies, with experience developing end-to-end projects including an AI Resume Screening Tool and a Hybrid Movie Recommendation System. Passionate about solving real-world problems through data-driven solutions and continuous learning
Skills & Tools
- Python
- SQL
- Scikit-learnScikit-learn
- Tensorflow
- KerasKeras
- FastAPI
- Git
- GitHub
- AWS
- GCPGCP
- Docker
- Numpy
- Pandas
- MatplotlibMatplotlib
- SeabornSeaborn
- CI/CDCI/CD
- RAGRAG
- LangchainLangchain
- Power BIPower BI
- TableauTableau
- Prompt Engineering,Prompt Engineering,
- OpenCvOpenCv
- Machine LearningMachine Learning
- Deep LearningDeep Learning
- TransformersTransformers
About Me
Hi, I'm Aryan Choudhary, an aspiring Machine Learning Engineer and Computer Engineering student passionate about building AI-powered solutions that solve real-world problems.
I enjoy working across the entire machine learning lifecycle—from data preprocessing and model development to deployment. During my AI/ML internship, I gained practical experience developing machine learning models using Python, Pandas, and Scikit-learn while contributing to real-world AI applications.
I have built end-to-end projects, including an AI Resume Screening Tool that uses NLP for semantic resume matching and a Hybrid Movie Recommendation System that combines content-based and collaborative filtering techniques. These projects have strengthened my skills in Python, Machine Learning, NLP, Docker, AWS, and Streamlit.
I'm always eager to learn new technologies, tackle challenging problems, and build intelligent applications that create meaningful impact. I am currently seeking opportunities where I can contribute, grow, and continue developing as an AI/ML Engineer.
Work Experience
Jan 2026 -June 2026
AI/ML Intern
ThinkNEXT Technology Private Limited
During My 6-month AI/ML internship at ThinkNEXT Technologies Pvt. Ltd.
I developed and deployed machine learning models, performed data preprocessing and analysis, integrated AI/ML solutions into real-world applications.
and collaborated using Git and GitHub to deliver efficient and scalable solutions.
Education
Sept 2023 – June 2026
BTech Computer Science (AI / ML)
Sri Sai University
2021 - 2023
Diploma in Computer Science
Government Polytechnic Kangra
Selected Work
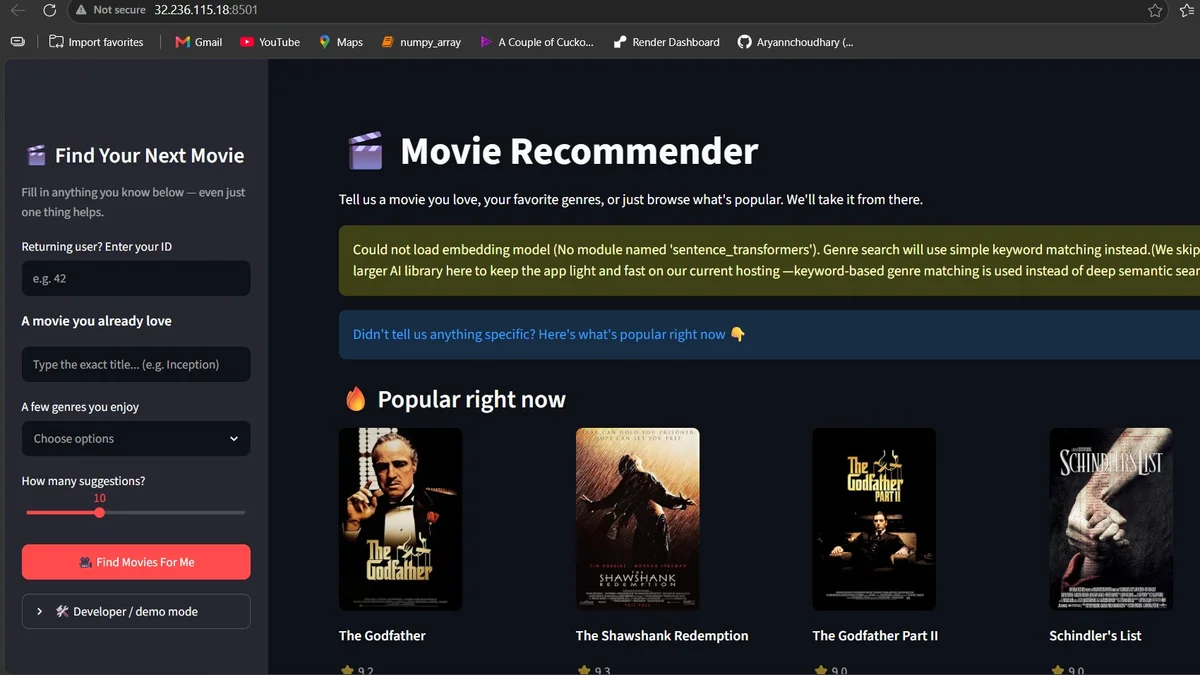
Hybrid Movie Recommendation System
Built a hybrid recommender combining FAISS content similarity search with SVD collaborative filtering, automatically routing users based on interaction history to solve the cold-start problem for new users and movies.
Evaluated performance using Precision@K, Recall@K, and Hit Rate@K, comparing warm vs. cold-start users against a popularity baseline
Deployed as a Dockerized Streamlit app on AWS EC2 with OMDb API integration, optimizing for free-tier hosting via precomputed embeddings and cached model loading
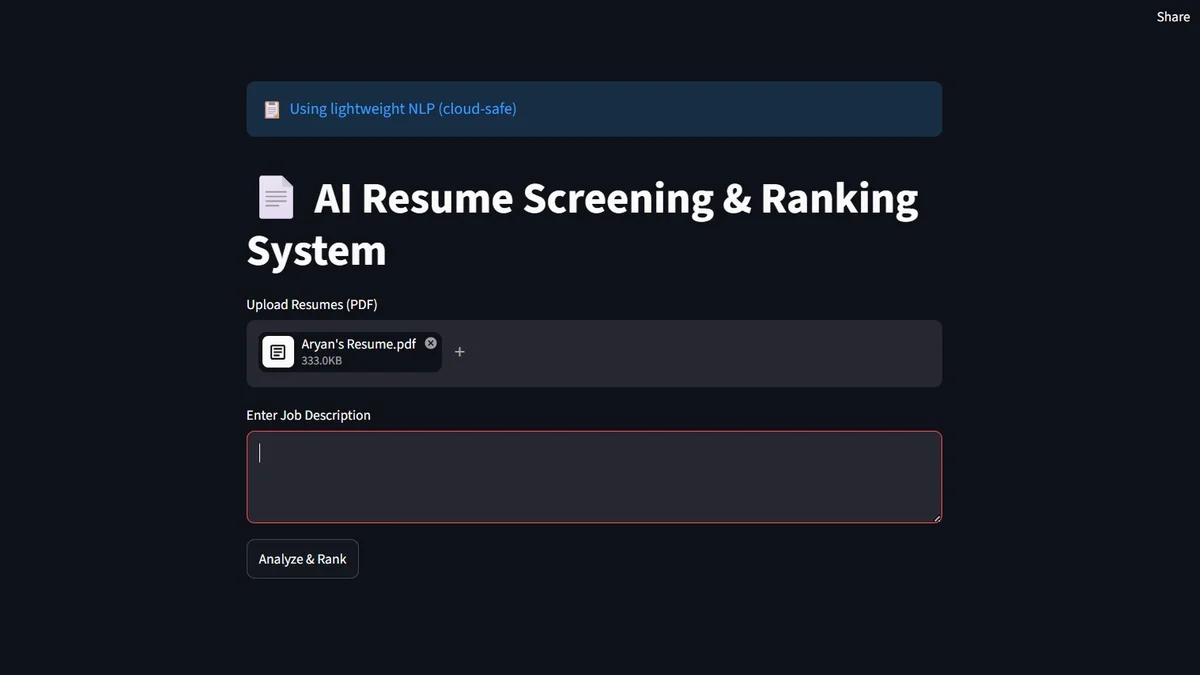
AI Resume Screening Tool
Developed a BERT-based semantic similarity (Sentence-Transformers) and keyword-based skill matching NLP resume ranking system to score candidate resumes against a job description, generating
a weighted ATS compatibility score.
Built automated resume parsing (name, email, phone, and skill extraction) from PDF uploads using
spaCy NER with regex fallback and deployed as an interactive Streamlit web app for real-time resume
evaluation and ranking.